

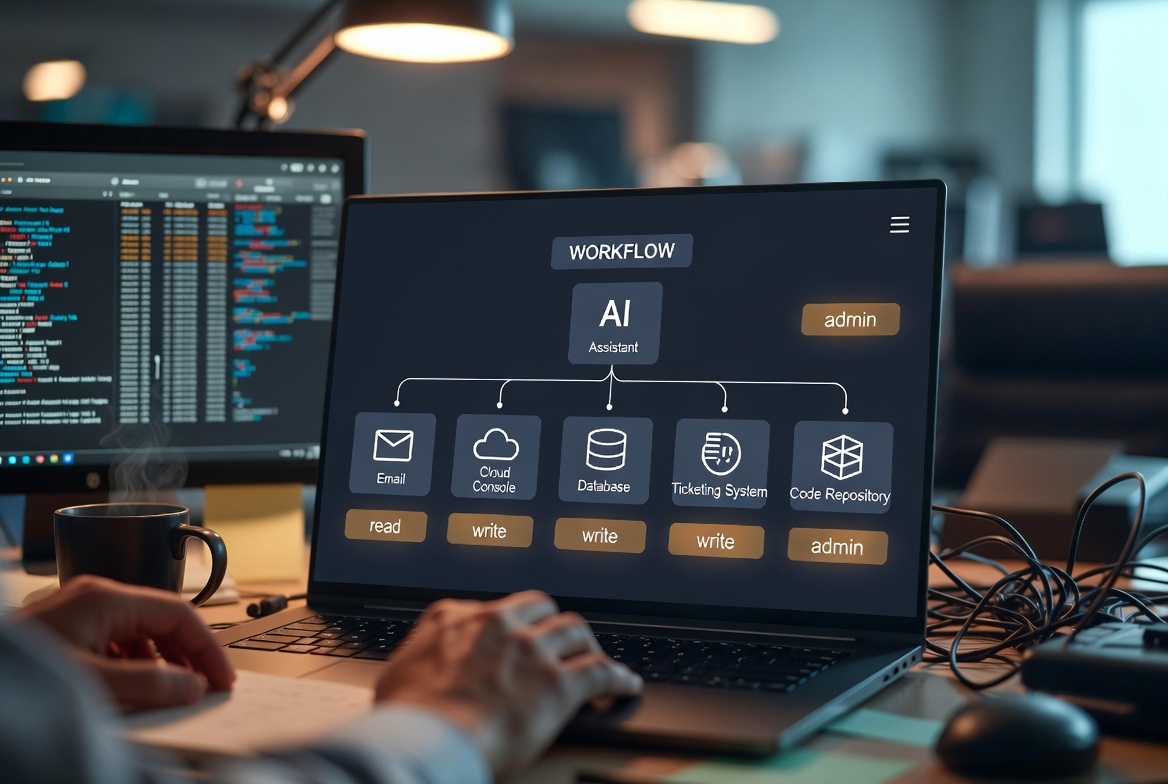
Tool-enabled AI agents are changing the security conversation. The risk is no longer limited to what a model says. The more important question is what the agent is allowed to do.
In many enterprise pilots, agents are being connected to tools, APIs, databases, ticketing systems, cloud consoles, code repositories, email, and internal documents. That makes them useful. It also gives them authority. When that authority is too broad, the agent becomes more than a chatbot. It becomes a new execution path inside the business.
A recent research paper on tool-enabled agents frames the issue clearly: many risks do not come from a new kind of software bug. They come from over-privileged tools, mismatches between user intent and tool capability, and authority leaking from the environment around the agent.
| Risk Area | Tool-enabled agents |
|---|---|
| Primary Issue | Agents connected to tools, APIs, credentials, and internal systems with more authority than the task requires |
| Main Failure Pattern | Over-privileged tools, capability-intent mismatch, and ambient authority (permissions inherited from the surrounding runtime) |
| Why It Matters | A bad instruction, prompt injection, or planning error can lead to real actions inside enterprise systems |
| Most Exposed Systems | Ticketing systems, cloud consoles, code repositories, databases, email, file stores, internal APIs, and automation platforms |
| Defender Priority | Inventory agents, restrict tool permissions, separate read and write actions, gate sensitive operations, and log every tool call |
Traditional chatbot risk is mostly about bad output: wrong answers, leaked information, or unsafe guidance. Tool-enabled agents change the failure mode. Once the agent can call APIs, modify records, send messages, open tickets, deploy code, or query internal systems, the risk becomes operational.
That is the privilege problem. Capability-intent mismatch is the gap between what the user asked for and what the connected tool is actually able to do. The agent may only be asked to summarize a ticket, but the connected tool may also allow it to edit, close, assign, or escalate that ticket. The user may only want a report, but the database credential may allow writes. The agent may only need read access to one folder, but the runtime may expose broader storage permissions.
In those cases, the model does not need to “break out” of the system. The system already gave it too much authority. A bad instruction, ambiguous request, prompt injection, or planning error can become a real action because the tool layer allows it.
This is why agent security looks less like content moderation and more like application security, identity governance, and workload isolation. The agent is not just generating text. It is operating through permissions, credentials, connectors, plugins, service accounts, and execution environments.
Security teams often focus on whether the model follows instructions. That matters, but it is not enough. In an agentic system, the security boundary extends into the tools the agent can call and the environment where those tools execute.
A prompt-injection attack is dangerous not only because it changes the model’s behavior, but because the changed behavior may be passed into a real tool with real authority.
This is where service accounts become important. Many agents run under API keys, OAuth tokens, cloud identities, or automation credentials. If those identities are broad, the agent inherits that reach. The business may think it deployed a narrow assistant, while the runtime quietly has access to a much larger set of systems.
The privilege problem usually does not start with a dramatic exploit. It often starts with convenience. Teams expose broad tools, reuse powerful credentials, or connect agents to production systems before the permission model is clearly defined.
One API key for too many actions. A team connects an agent to a production API using a key that can read, write, delete, and administer resources. The agent only needs one of those capabilities, but the credential exposes all of them.
Read tasks backed by write-capable tools. A user asks the agent to summarize data, but the connected database role can also modify or delete records. The safe task is backed by an unsafe permission model.
Tools grouped for convenience instead of control. Developers expose broad “workspace,” “admin,” or “automation” tools because they are easier to integrate. The agent then receives a large action surface that is difficult to reason about or audit.
Runtime secrets exposed to the agent workflow. Credentials stored in environment variables, logs, debugging output, or shared execution contexts can become accessible during agent operation. Once secrets appear in the workflow, they can be leaked, reused, or mishandled.
No reliable record of why an action happened. If tool calls are not logged with the user request, model decision, tool input, tool output, approval state, and final result, incident response becomes guesswork. That is especially dangerous when the agent touches production systems.
This is not a reason to block every agent project. It is a reason to treat agent deployment as a security architecture problem, not only a productivity experiment. The goal is to make sure agents can perform useful work without becoming uncontrolled execution paths inside the enterprise.
Inventory every agent and connected tool. Security teams need to know which agents exist, what tools they can call, what identities they use, what systems they touch, and whether they can perform write actions.
Separate read, write, and admin capabilities. Do not give one tool broad access for convenience. A summarization agent should not use the same credential as an automation agent that can update records or trigger workflows.
Use least privilege at the tool level. Permissions should be scoped by action, object, environment, and business need. If an agent only needs to read one repository, it should not receive organization-wide repository access.
Gate sensitive actions. Require human confirmation for actions such as sending external messages, modifying production data, changing access, deploying code, rotating secrets, or triggering financial and operational workflows.
Make approval prompts specific. A vague approval prompt such as “Proceed?” is weak. A useful approval should show what system will be touched, what data will be changed, what account will perform the action, and what the expected result is.
Log the full decision chain. Record the user request, model plan, selected tool, tool parameters, approval status, execution result, and affected system. This is essential for audit, debugging, and incident response.
Isolate execution environments. Avoid letting agents share broad runtime credentials, shared filesystem access, or unrestricted network access. The agent’s environment should be treated like any other privileged workload.
Test for misuse, not only accuracy. A model evaluation that only checks answer quality will miss the real risk. Agent testing should include permission checks, tool misuse scenarios, ambiguous prompts, prompt injection attempts, and approval bypass attempts.
ByteVanguard tracks AI security, exploited vulnerabilities, CISA KEV activity, and enterprise threat intelligence. Subscribe for weekly briefings.
If you find ByteVanguard useful, you can support the site and help keep the analysis independent.
Support the analysis