Palo Alto Networks Unit 42
Phantom Squatting: AI-Hallucinated Domains as a Software Supply Chain Vector


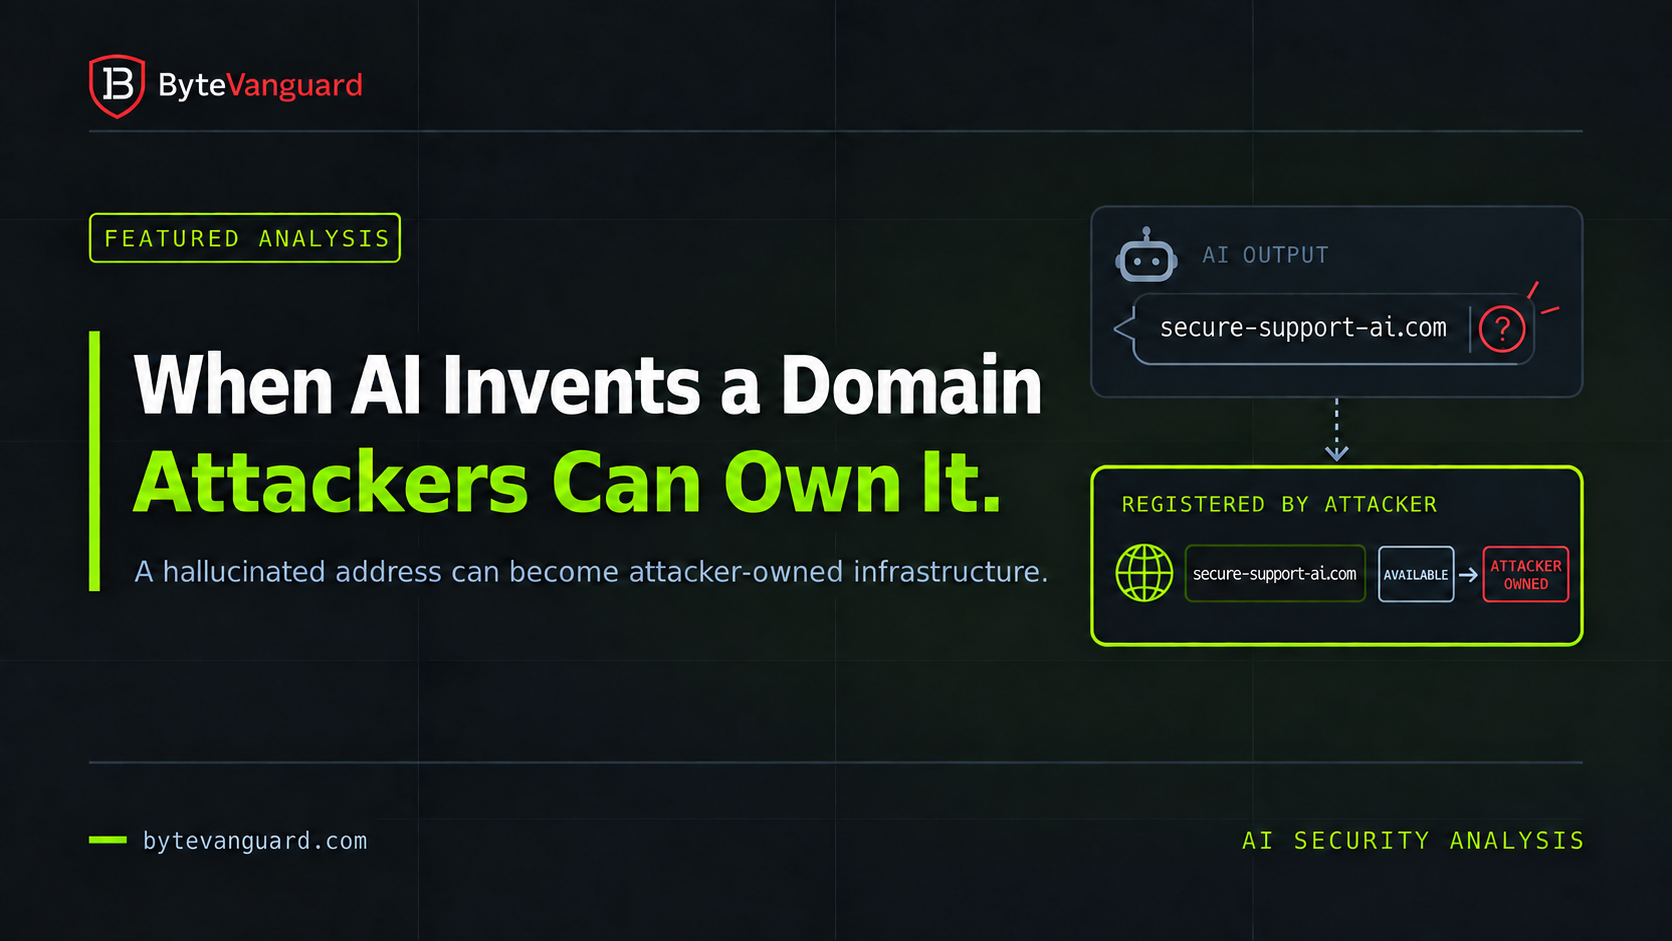
Phantom squatting turns an AI-generated web address from fiction into attacker-controlled infrastructure—and may allow a trusted assistant to deliver the victim.
An AI assistant invents a convincing support portal.
Nobody owns the domain.
An attacker registers it.
The next time the model produces the same answer, the fictional address leads somewhere real.
This is phantom squatting: the registration and weaponization of domains that artificial intelligence systems are likely to hallucinate.
Traditional phishing begins with an attacker creating a lure and finding a way to deliver it. Phantom squatting reverses that order. The model creates the plausible destination first. The attacker discovers the prediction, purchases the address, and waits for the AI system to send someone there.
The attacker does not need to compromise the model, poison its training data, or breach the AI provider.
The attacker only needs to own the place the model invented.
Language models generate responses by predicting plausible sequences of words. That ability allows them to produce fluent explanations, realistic code, and names that sound as though they should exist.
Sometimes they do not.
A model asked for an employee-benefits portal might combine a company name with words such as “benefits,” “login,” or “support.” A coding assistant might produce a believable API hostname. A research agent could offer a convincing address for a government program, bank service, or technical-documentation site.
At the moment the answer is generated, the destination may be harmless because nothing exists there. But domain names operate on ownership, not intent. If the address is unregistered, almost anyone can buy it.
The invention then stops being merely a model error. It becomes a location on the public internet controlled by whoever registered it first.
“The attacker does not have to make the domain famous. The model only has to make it plausible.“
Reputation-based security systems usually identify malicious infrastructure after it develops an observable history.
A domain may be blocked because it appeared in earlier attacks, served malware, shared infrastructure with known threats, triggered sandbox detections, or was reported by users.
A newly registered phantom domain begins with none of those signals.
It may have no blocklist entry, no established reputation score, no previous campaign activity, and no known connection to criminal infrastructure. During its earliest—and potentially most valuable—period, it can resemble any other newly created website.
Unit 42 describes this as a zero-reputation bypass. The domain is not considered safe because investigators verified its ownership or purpose. It is simply too new for conventional threat intelligence to have reached a conclusion.
The AI recommendation supplies the credibility that the domain itself has not earned.
| Attack element | Traditional phishing | Phantom squatting |
|---|---|---|
| Lure creation | The attacker creates a message designed to look legitimate | The AI produces a plausible destination in an ordinary response |
| Delivery channel | Email, text message, advertisement, or social media | A trusted assistant, coding tool, research agent, or automated workflow |
| Attacker action | Push the malicious link toward selected targets | Register a predicted hallucination and wait for targets to arrive |
| Early reputation | May reuse infrastructure already associated with abuse | Can begin as a newly registered domain with no malicious history |
| Primary trust signal | The message appears to come from a familiar sender | The address is presented by an AI system the user already trusts |
In research published in June 2026, Palo Alto Networks Unit 42 examined how language models generate domains associated with well-known organizations.
The researchers analyzed 913 global brands and submitted 685,339 URL queries across multiple configurations of two different models. Those queries produced approximately 2.1 million URLs.
Among them, Unit 42 reported 13,229 generated URLs confirmed as malicious and approximately 250,000 hallucinated domains that remained unregistered.
These figures do not mean that every invented address will become an attack site. They demonstrate something more operationally important: models can produce a large, discoverable inventory of plausible destinations, and many can potentially be purchased before defenders know they matter.
The research also documented real-world cases in which domains identified through its discovery process were later registered and weaponized. In one case, researchers reported detecting a predicted domain 23 days before an attacker registered it and deployed a phishing kit.
This creates a narrow but valuable defensive window. A company may be able to identify a domain its AI systems are likely to invent before an adversary occupies it.
Phantom squatting extends a problem already observed in AI-generated software development.
A coding model may recommend a library that does not exist in PyPI, npm, or another package registry. If an attacker publishes malicious code under that invented name, a developer following the generated installation command may retrieve the attacker’s package.
This related technique is commonly called slopsquatting.
Research presented at USENIX Security examined hundreds of thousands of AI-generated code samples. It reported hallucinated-package rates of at least 5.2% for the commercial models tested and 21.7% for the open-source models tested. The researchers identified 205,474 unique hallucinated package names.
Phantom squatting applies the same adversarial logic to web infrastructure.
The model invents a software package. An attacker publishes code under that name and waits for a developer or coding agent to install it.
The model invents a web address. An attacker registers the domain and waits for a person or agent to visit it.
The suggested name looks structurally correct, but nothing independently confirms who controls it.
Turning a predicted hallucination into an owned package or domain can be faster than waiting for defenders to classify it.
Both techniques exploit the gap between a plausible name and a verified identity.
A person who follows an invented address may still stop when the page requests credentials, initiates a download, or behaves unexpectedly.
An autonomous agent may not.
AI agents increasingly retrieve documentation, download dependencies, call APIs, submit information, follow redirects, and process responses without pausing for approval at every step.
Consider a coding agent instructed to configure a new integration:
No employee clicked a suspicious email. No vulnerability in the AI model was required. Each component may have behaved as designed, but the workflow crossed from generated text into hostile infrastructure without an independent identity check.
The relevant security boundary is the moment generated text becomes an external action.
“When an AI can invent a destination and then contact it, hallucination becomes an outbound-security problem.“
Typosquatting anticipates human error. An attacker registers a misspelling of a popular domain and waits for someone to type it incorrectly.
Phantom squatting anticipates machine output.
The attacker searches for names a model is likely to generate and registers them before the recommendation reaches a victim.
This difference complicates brand protection. Organizations commonly monitor missing letters, added hyphens, alternative top-level domains, and visually similar characters. A hallucinated address may not resemble the official domain closely enough to appear on those lists.
Instead, it may be a semantically plausible service name containing words such as “portal,” “developer,” “claims,” “connect,” “verify,” “support,” or “api.” It looks credible because it reflects the type of name a real organization might have selected.
| Technique | What the attacker predicts | Typical pattern |
|---|---|---|
| Typosquatting | A human will mistype a known address | Missing, duplicated, or transposed letters |
| Combosquatting | A human will trust a brand combined with a familiar term | Brand plus “login,” “secure,” or “support” |
| Homograph attack | A human will overlook visually similar characters | Lookalike letters from different alphabets |
| Phantom squatting | An AI will repeatedly invent the same plausible destination | A nonexistent portal, API, or service recommended by the model |
Eliminating every hallucinated URL is unrealistic. Preventing generated destinations from receiving automatic trust is achievable.
AI interfaces should distinguish between a link retrieved from a verified source and an address created as part of generated text.
To a user, both may appear as identical hyperlinks. Technically, they represent different levels of evidence.
A retrieved URL can be connected to an indexed page, approved document, search result, or internal directory. A generated URL may be nothing more than a statistically plausible sequence of characters.
Applications should avoid allowing models to invent destinations when a validated directory can supply them instead. A support assistant should retrieve the official help portal from an approved knowledge base. A coding agent should select API endpoints from verified vendor documentation. An internal agent should use centrally managed service records rather than constructing hostnames from memory.
When a previously unseen destination is unavoidable, the workflow should pause before transmitting sensitive information or executing downloaded content.
Warnings inside a chat interface will not protect every automated workflow. The most reliable controls must operate outside the model.
Organizations should log the URLs generated, resolved, visited, and contacted by AI-enabled systems. Useful signals include newly registered domains, first-seen destinations, unexpected redirects, certificate mismatches, direct IP connections, and outbound requests carrying sensitive headers or unusual volumes of data.
The objective is not to monitor every sentence an employee writes. It is to make consequential machine actions visible.
For years, defenders have warned users that a familiar logo does not prove who owns a website. AI creates the next version of that lesson: a confident recommendation does not prove that the destination exists for the reason the model claims.
The web makes this form of hallucination unusually dangerous because names can be purchased.
A fabricated historical event remains false. An invented person remains fictional. But an invented domain can be registered in minutes, connected to a server, and transformed into an operational attack asset.
The answer is not to expect perfect output from probabilistic systems. It is to stop an unverified string from becoming a trusted destination merely because a model produced it fluently.
An AI can invent the address. An attacker can own it. Security must decide whether anyone—or anything—is allowed to go there.
If you find ByteVanguard useful, you can support the site and help keep the analysis independent.
Support the analysis